Google releases Gemini 3.8 Flash for long-horizon coding
Google has released Gemini 3.8 Flash as a generally available model for long-horizon coding, autonomous agents and enterprise workflows. The API keeps the introductory price of Gemini 3.7 Flash, with a one-million-token input limit and 65,536-token output limit.
Synthesized via Fish Audio S2.1 Pro in British English. Natural editorial summary, not verbatim reading.
Key Takeaways
- check_circleGoogle announced Gemini 3.8 Flash on 2 September 2026 and lists it as generally available through the Gemini API.
- check_circleThe model has a 1,048,576-token input limit, a 65,536-token output limit, and supports thinking at low, medium and high effort.
- check_circleGoogle lists an introductory price of $0.75 per million input tokens and $3.75 per million output tokens through 31 December 2026.
- check_circleAIMI saw the official API route before the announcement, then recorded OpenRouter and OpenCode Zen routes later that afternoon. These are availability timestamps, not separate maker releases.
Google's third Flash release in six weeks
Google announced Gemini 3.8 Flash on 2 September 2026. The company describes it as its most intelligent Flash model, built for long-horizon software engineering, autonomous agents and complex enterprise workflows.
Google says this is the third Gemini Flash release in six weeks. That is the company's release cadence claim, not evidence that any other provider or model maker was responding to it. The same announcement also introduced Gemini 3.8 Flash Cyber, a separate version for trusted defenders through the Fairwind Program. This article covers the generally available Gemini 3.8 Flash model.
What the API supports
The Gemini API documentation lists a 1,048,576-token input limit and a 65,536-token output limit. Thinking is supported at low, medium and high effort. Minimal effort is not supported and returns an error.
The documented capabilities include caching, code execution, computer use in preview, file search, function calling, Google Maps grounding, image understanding, search grounding, structured outputs and URL context. Audio generation, image generation and the Live API are not supported by this model.
Pricing and access
Google lists a free tier for Gemini 3.8 Flash. Paid standard pricing is $0.75 per million input tokens and $3.75 per million output tokens, including thinking tokens, through 31 December 2026. From 1 January 2027, the listed prices rise to $1.50 and $7.50 respectively.
The model code for direct API use is gemini-3.8-flash. OpenRouter lists google/gemini-3.8-flash and google/gemini-3.8-flash:batch, while OpenCode Zen lists gemini-3.8-flash. The provider registries confirm route availability, but they do not turn those routes into additional Google releases.
How the release surfaced in AIMI
AIMI first observed models/gemini-3.8-flash on Google's official models endpoint at 16:46:56 SAST. Google's announcement was published at 15:00 UTC, or 17:00:00 SAST, so the endpoint was visible 13 minutes and 4 seconds before the public announcement. The first-seen time is an observation, not the release time.
AIMI first saw the standard OpenRouter route at 17:18:58 SAST, exactly 18 minutes and 58 seconds after the announcement. The batch route appeared at 17:35:00 SAST, 16 minutes and 2 seconds after the standard route. OpenCode Zen followed at 18:55:08 SAST, 1 hour, 55 minutes and 8 seconds after the announcement. The route sequence shows distribution across providers during the day, not a chain of separate model launches.
There were no earlier verified releases in this input batch to combine with Gemini 3.8 Flash. The official Google announcement and API changelog establish the maker release. AIMI's endpoint records establish when the routes became visible to the monitoring system.
What developers should check
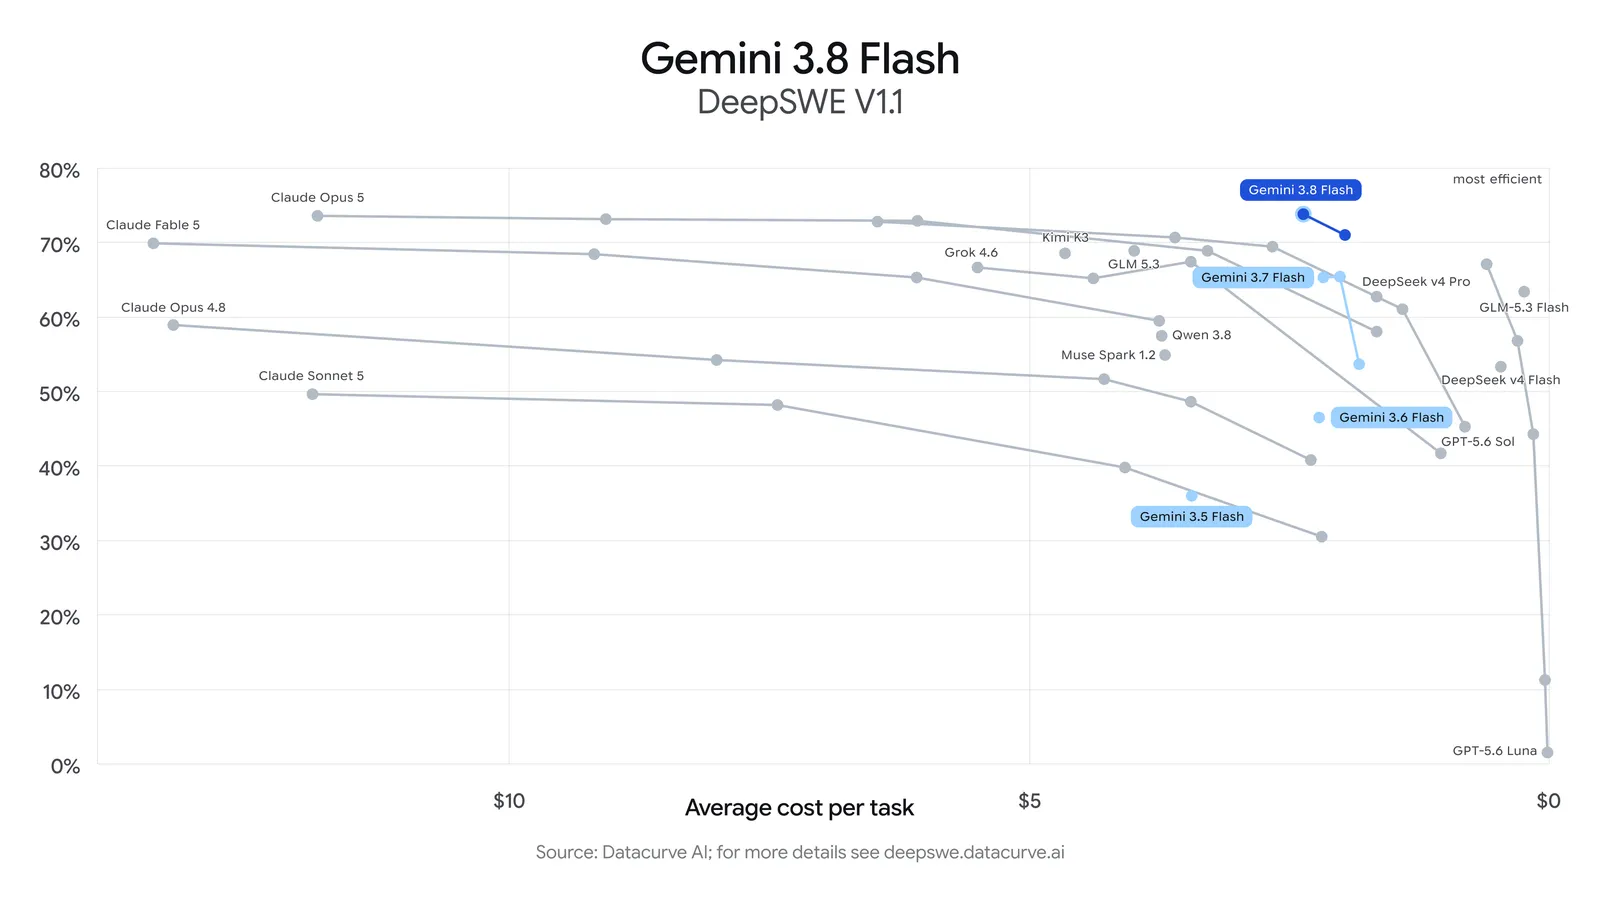
Gemini 3.8 Flash is aimed at workloads where a task can run for many steps and use tools along the way. Google says the model may use more reasoning tokens at higher effort levels, so the token budget and price should be part of any production test.
Before switching a live application, test the exact provider route rather than assuming that the direct Google API, OpenRouter and OpenCode Zen behave identically. Check tool schemas, effort controls, rate limits, retention terms and current pricing. AZ Labs can provide one integration layer for teams that need to compare routes without rewriting the application each time.
Visual Architecture & Benchmarks
Official maker scorecard graphics, diagrams, and benchmarks. Click any image to inspect in full resolution.
Frequently Asked Questions
Was Gemini 3.8 Flash released on 2 September 2026?
Yes. Google published its official Gemini 3.8 Flash announcement on 2 September 2026 and the Gemini API changelog marks the model generally available on that date.
What is Gemini 3.8 Flash's context limit?
The Gemini API documentation lists a 1,048,576-token input limit and a 65,536-token output limit.
What does Gemini 3.8 Flash cost?
Google lists a free tier. Paid standard pricing is $0.75 per million input tokens and $3.75 per million output tokens through 31 December 2026. The listed prices increase on 1 January 2027.
Where is Gemini 3.8 Flash available?
The model is available directly through the Gemini API as gemini-3.8-flash. AIMI also recorded routes on OpenRouter as google/gemini-3.8-flash and google/gemini-3.8-flash:batch, and on OpenCode Zen as gemini-3.8-flash.
Does the endpoint timeline show multiple Gemini 3.8 releases?
No. The timeline shows one Google maker release followed by provider route additions. Endpoint first-seen times describe when AIMI observed access, not separate model announcements.
Related Frontier Models & Releases
Explore verified specifications, benchmark results, and route pricing across alternative models in this class.
Gemini 3.7 Flash Is Now Generally Available
Google has released Gemini 3.7 Flash as a stable model for coding, agent workflows and multimodal reasoning. It has a 1,048,576-token input limit, 65,536-token output, and direct API pricing from $0.75 per million input tokens through 2026.
Meta Releases Muse Spark 1.3: 1M Multimodal Reasoning Model for Autonomous Agent Workflows
Meta Superintelligence Labs has published Muse Spark 1.3, an open-weights frontier agent model with 1,048,576 context tokens and comprehensive multimodal comprehension.
Google Releases Gemini 3.6 Flash: High-Efficiency Multimodal Intelligence for Fast Agent Loops
Google launched Gemini 3.6 Flash on 21 July 2026 alongside 3.5 Flash-Lite and 3.5 Flash Cyber, cutting output token usage by 17% against 3.5 Flash at $0.75 per million input tokens.