Google Releases Gemini 3.6 Flash: High-Efficiency Multimodal Intelligence for Fast Agent Loops
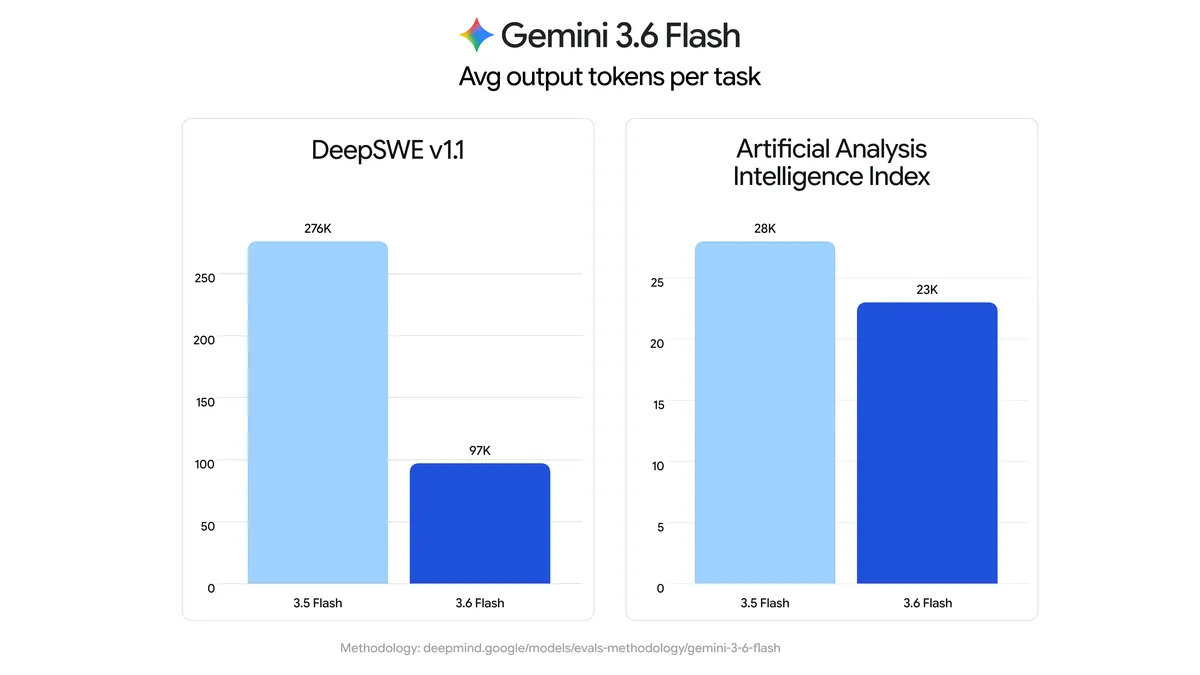
Google launched Gemini 3.6 Flash on 21 July 2026 alongside 3.5 Flash-Lite and 3.5 Flash Cyber, cutting output token usage by 17% against 3.5 Flash at $0.75 per million input tokens.
| Platform | Route Identifier | Context | Max Output | Rate / Tier | Status |
|---|---|---|---|---|---|
| Google AI Studio | gemini-3.6-flash | 1.05M tokens (1,048,576) | 66K tokens (65,536) | $0.75 / $3.75 per 1M tokens ($0.075 cached prompt) | active |
| OpenRouter | google/gemini-3.6-flash | 1.05M tokens (1,048,576) | 66K tokens (65,536) | $0.75 / $3.75 per 1M tokens | active |
Key Takeaways
- check_circleGemini 3.6 Flash processes text, high-res image, multi-hour audio, video, and code in a native end-to-end transformer.
- check_circleContext window of 1,048,576 tokens paired with ultra-low latency makes it ideal for live voice agents and streaming video analysis.
- check_circleExtremely economical pricing at $0.75 per million prompt tokens and $3.75 per million completion tokens, with cache hits at $0.075/M.
- check_circleAIMI registered the production route on 21 July 2026 at 17:12:13 SAST.
True Native Omnimodal Processing
Gemini 3.6 Flash represents Google DeepMind's premier high-velocity engine. Rather than relying on separate audio transcribers or vision encoders, Gemini 3.6 Flash natively maps audio waveforms, video frames, and text tokens into a shared semantic latent space.
This allows for immediate temporal reasoning—such as pinpointing exact visual occurrences in a 60-minute video or transcribing overlapping multi-speaker audio with flawless diarization.
Sub-Second Agentic Velocity
With time-to-first-token (TTFT) clocking under 280ms, Gemini 3.6 Flash eliminates the awkward lag in conversational voice applications and interactive copilot sidebars.
Visual Architecture & Benchmarks
Official maker scorecard graphics, diagrams, and benchmarks. Click any image to inspect in full resolution.
Frequently Asked Questions
What input formats does Gemini 3.6 Flash accept?
Gemini 3.6 Flash natively processes text, image files (JPEG, PNG, WebP), audio recordings (MP3, WAV), video files (MP4), and documents (PDF, CSV, TXT).
Related Frontier Models & Releases
Explore verified specifications, benchmark results, and route pricing across alternative models in this class.
Google releases Gemini 3.8 Flash for long-horizon coding
Google has released Gemini 3.8 Flash as a generally available model for long-horizon coding, autonomous agents and enterprise workflows. The API keeps the introductory price of Gemini 3.7 Flash, with a one-million-token input limit and 65,536-token output limit.
Anthropic Releases Claude Sonnet 5: The Benchmark Leader for High-Speed Coding and Autonomous Agents
Anthropic has introduced Claude Sonnet 5, offering 1M context processing, adaptive thinking effort controls, and unmatched throughput for software engineering.
DeepSeek releases V4.1 Flash with native multimodal vision, 552B MoE and lower API rates
DeepSeek has launched DeepSeek-V4.1-Flash, a 552B-parameter mixture-of-experts model featuring a novel Causal Encoder–Decoder architecture with just 8B active input and 16B active output parameters. The release brings native vision, compresses KV cache storage by up to 8x, and slashes off-peak API pricing to $0.15 per million input tokens.